Thread Hierarchy
The CUDA programming model's organization of parallel execution into threads, thread blocks and thread block grids.
The thread hierarchy is a key abstraction of the CUDA programming model, alongside the memory hierarchy. It organizes the execution of parallel programs into levels, from individual threads up to the whole GPU.
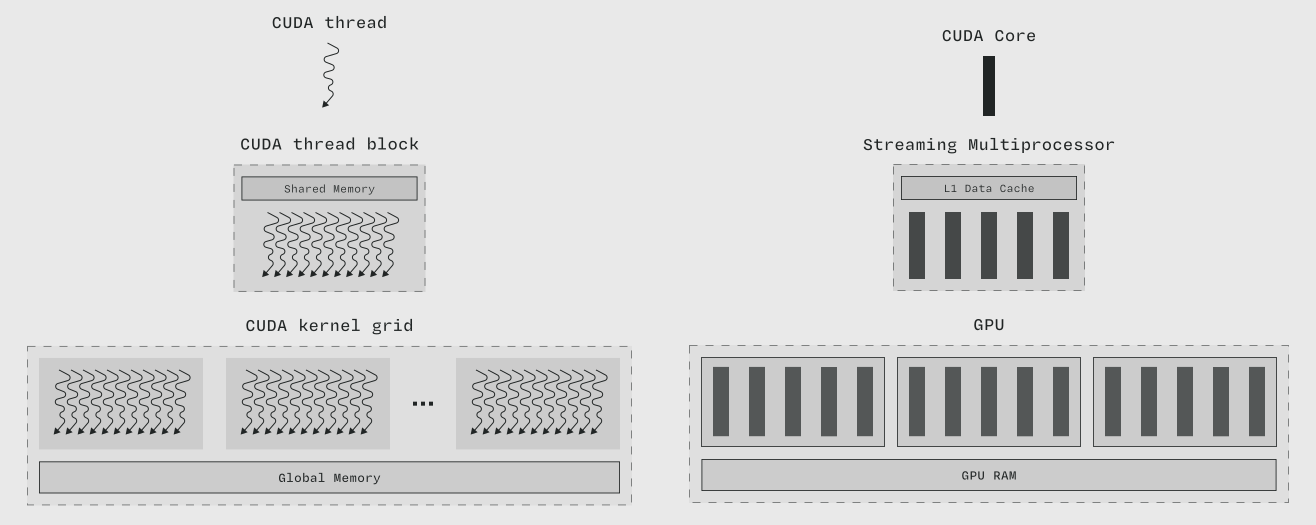
Threads#
At the bottom are individual threads. Like a thread of execution on a CPU, each CUDA thread executes a stream of instructions. The hardware that carries out arithmetic and logic instructions is called cores, or sometimes "pipes". Threads are selected for execution by the Warp Scheduler.
Thread blocks#
The middle level is thread blocks, known as cooperative thread arrays in PTX and SASS.
- Each thread has a unique, index-based identifier within its block, which makes it easy to assign work by index into input or output arrays.
- All threads in a block are scheduled simultaneously onto the same Streaming Multiprocessor (SM).
- They can coordinate through shared memory and synchronize with barriers.
Grids#
At the top, thread blocks are organized into a thread block grid that spans the entire GPU. Blocks are strictly limited in how they coordinate and communicate. They execute concurrently with no guaranteed order, so CUDA programs must be correct under any interleaving of blocks, from fully serial to fully parallel. That means, for instance, that blocks cannot synchronize with barriers.
Like threads, each block has a unique, index-based identifier for assigning work by array index.
Key idea Threads in a block can cooperate; blocks in a grid must be independent.
Mapping onto hardware#
The hierarchy maps directly onto the GPU hardware:
| Software level | Runs on |
|---|---|
| Thread | An individual core |
| Thread block | One SM |
| Grid | All available SMs on the device |
Related#
- Memory Hierarchy: the matching memory at each level
- Warp: the hardware grouping of threads between thread and block
- Streaming Multiprocessor: where blocks run