Shared Memory
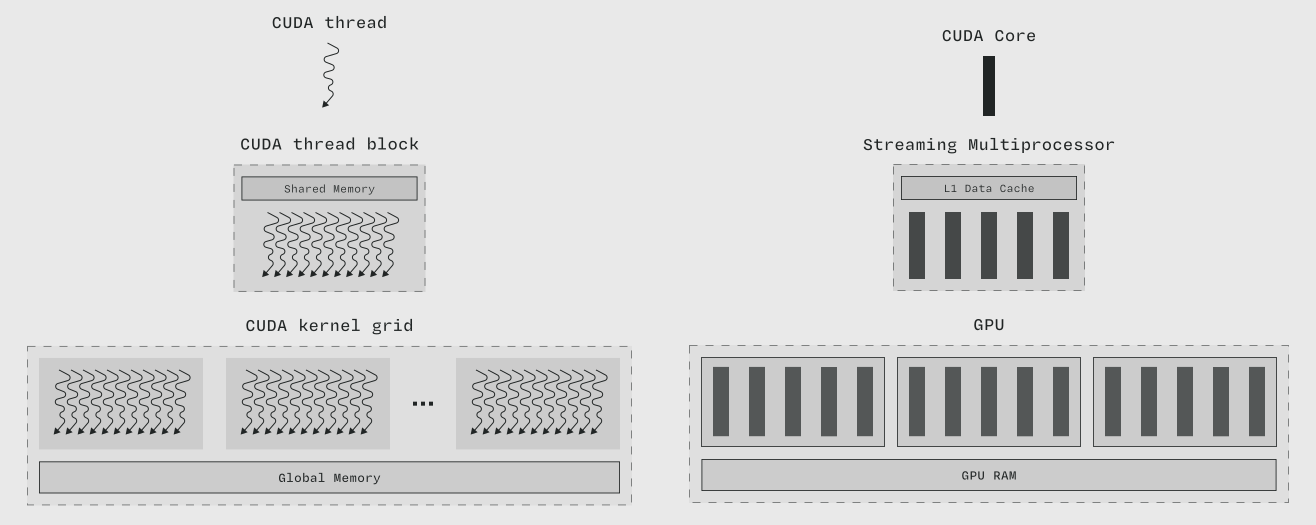
The memory shared by the threads of a thread block, much smaller but much faster than global memory, stored in the SM's L1 data cache.
Shared memory is the level of the memory hierarchy that matches the thread block level of the thread hierarchy in the CUDA programming model. It is generally much smaller than global memory, but much faster in both throughput and latency.
A typical kernel pattern#
Because of this trade-off, a fairly typical kernel looks like this:
- Load data from global memory into shared memory.
- Perform many arithmetic operations on that data using the CUDA Cores and Tensor Cores.
- Optionally, synchronize threads within the thread block with barriers while doing those operations.
- Write data back to global memory, optionally using atomics to prevent races across thread blocks.
Key idea Stage data in shared memory so it is loaded from slow global memory once and reused many times.
Hardware#
Shared memory is stored in the L1 data cache of the GPU's Streaming Multiprocessor (SM).
Related#
- L1 Data Cache: the hardware behind shared memory
- Bank Conflict: a common shared memory performance pitfall
- Kernel: a tiled matmul example using shared memory