Thread Block
The middle level of the CUDA thread hierarchy, a group of threads that run on one SM and can coordinate with each other.
A thread block is the level of the CUDA programming model's thread hierarchy between a grid and a thread. It is the abstract counterpart of the concrete cooperative thread arrays in PTX and SASS.
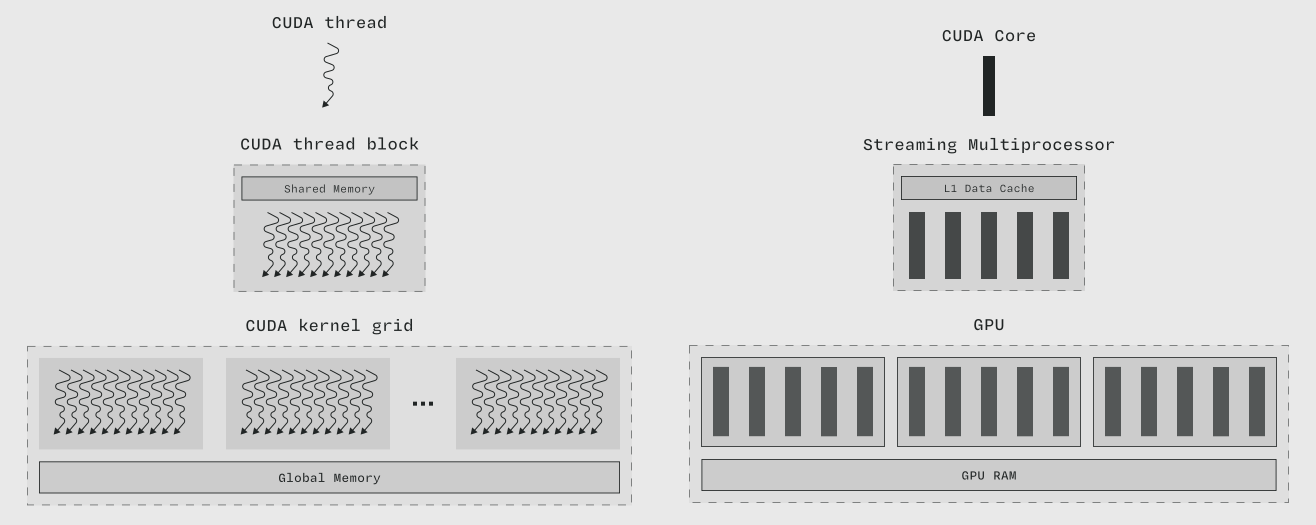
Blocks are the smallest unit of thread coordination the programming model exposes. A block executes on a single Streaming Multiprocessor.
Blocks must execute independently, so that any execution order is valid: fully serial in any order, or any interleaving.
Key idea Threads inside a block can cooperate; blocks themselves must not depend on each other's order.
Size#
A single CUDA kernel launch produces one or more thread blocks (as a thread block grid), and each block contains one or more warps. Blocks can be any size up to a limit of 1024 threads on current devices, but they are typically multiples of the warp size (32 on current devices).
Related#
- Cooperative Thread Array: how blocks are implemented in PTX and SASS
- Shared Memory: the memory a block shares
- Thread Block Grid: the level above