Global Memory
The top level of the CUDA memory hierarchy, accessible to every thread in a grid for the life of the program, stored in GPU RAM.
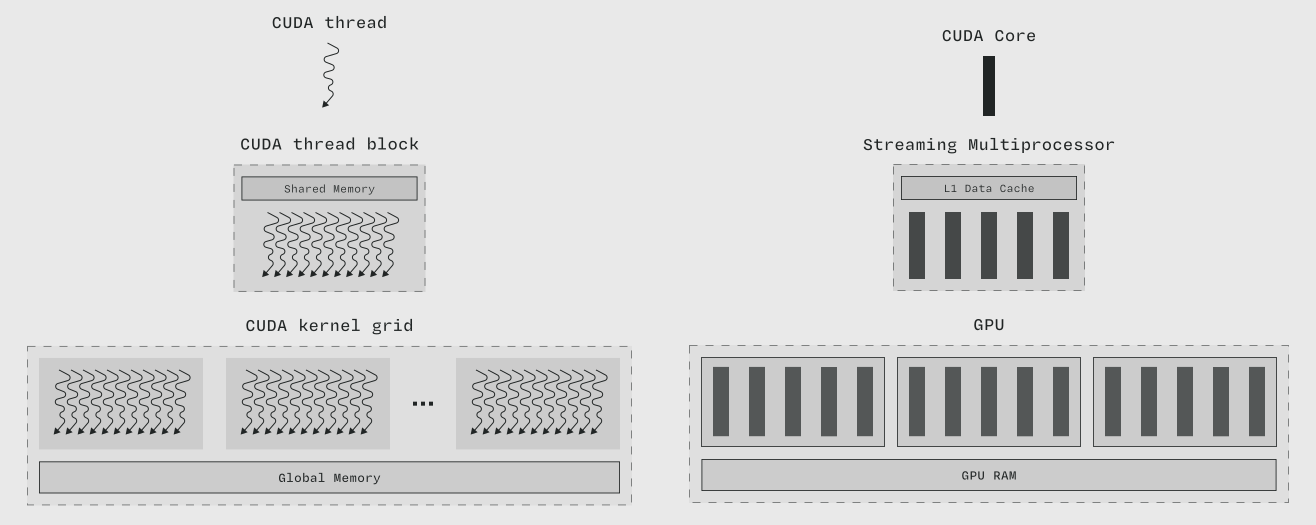
Global memory is the highest level of the memory hierarchy in the CUDA programming model. In that model, each level of the thread hierarchy has matching memory used for coordination and communication, managed by the programmer rather than by the hardware or a runtime.
Scope and lifetime#
Global memory is global in both scope and lifetime:
- Scope: every thread in a thread block grid can access it.
- Lifetime: it lasts as long as the program runs.
Synchronization#
As with CPU memory, access to data structures in global memory can be synchronized across all accessors with atomic instructions. Within a cooperative thread array, access can be synchronized more tightly, for example with barriers.
Implementation and allocation#
Global memory is typically implemented in the GPU's RAM. It is allocated from the host using a memory allocator from the CUDA Driver API or the CUDA Runtime API.
A naming collision#
"Global" unfortunately collides with the __global__ keyword in CUDA C/C++. That keyword marks functions launched on the host but run on the device (kernels), whereas global memory lives only on the device. Early CUDA architect Nicholas Wilt wryly notes in his CUDA Handbook that this choice was made "for maximum developer confusion".
Related#
- GPU RAM: the hardware that holds global memory
- Shared Memory: the faster, smaller level below
- Memory Coalescing: how to access global memory efficiently